Automate document tagging for better searchability
Version 1. 2
April 2022
Nutrient Document Searchability Tagging improves how documents in SharePoint are found and classified. It generates metadata from a document’s contents and tags the document with it, drawing on rules, taxonomies, barcodes, PDF forms, XMP and NLP services.
The business problem: Drowning in data, thirsting for information
In a survey published as Well-known findability challenges in the AI-hype (2019) on Findwise(opens in a new tab), 55% of respondents struggled to find information within their own organizations. Improvement had stalled for several years. The obstacles include lack of resources, poor information quality, and insufficient metadata management.
AI and machine learning add a further challenge: Organizations now manage vast amounts of structured and unstructured data. Demand has grown for solutions that keep data findable, accessible, interoperable and reusable, in line with the FAIR principles. Enterprise search tools built on AI and Natural Language Processing (NLP) are being adopted to meet it.
Document stores such as Microsoft SharePoint keep growing, and the expectation of finding things in them grows with it. That calls for a way to enrich the (raw) data automatically, by extracting the valuable information it holds. Findability is a critical need for business success.
The extracted information can be added to the documents in SharePoint as metadata, which is also known as tagging. Metadata is what makes information in SharePoint findable and accurate. Documents there often lack the key metadata a straightforward metadata search needs. A query then returns every document containing the search term, with no way to refine the results further.
Good metadata lifts a document’s ranking in search results, because a query match against metadata counts for more than one against the document text. Faceted navigation then refines those results further, applying filters on additional metadata one at a time until the right document surfaces.
Organizations still lean heavily on manual tagging, especially for nuanced or complex data. Manual work is inconsistent and subjective, though, which produces poor metadata quality and inefficiencies(opens in a new tab).
Manual tagging is slow and subjective, so satisfaction with its accuracy stays low. Inconsistencies in metadata(opens in a new tab) damage data discoverability and quality, and the business operations that depend on them.
Automated tagging is the practical answer. Manual inspection and correction can then complement the generated metadata, improving the consistency, accuracy, speed and cost of tagging.
The solution: Nutrient Document Searchability Tagging
Nutrient Document Searchability Tagging extracts or generates metadata from new and existing documents in SharePoint, then tags those documents with it. Configuration decides which metadata it goes after. It is a stand-alone client application, and it installs on any computer that can reach the SharePoint server.
Architecture
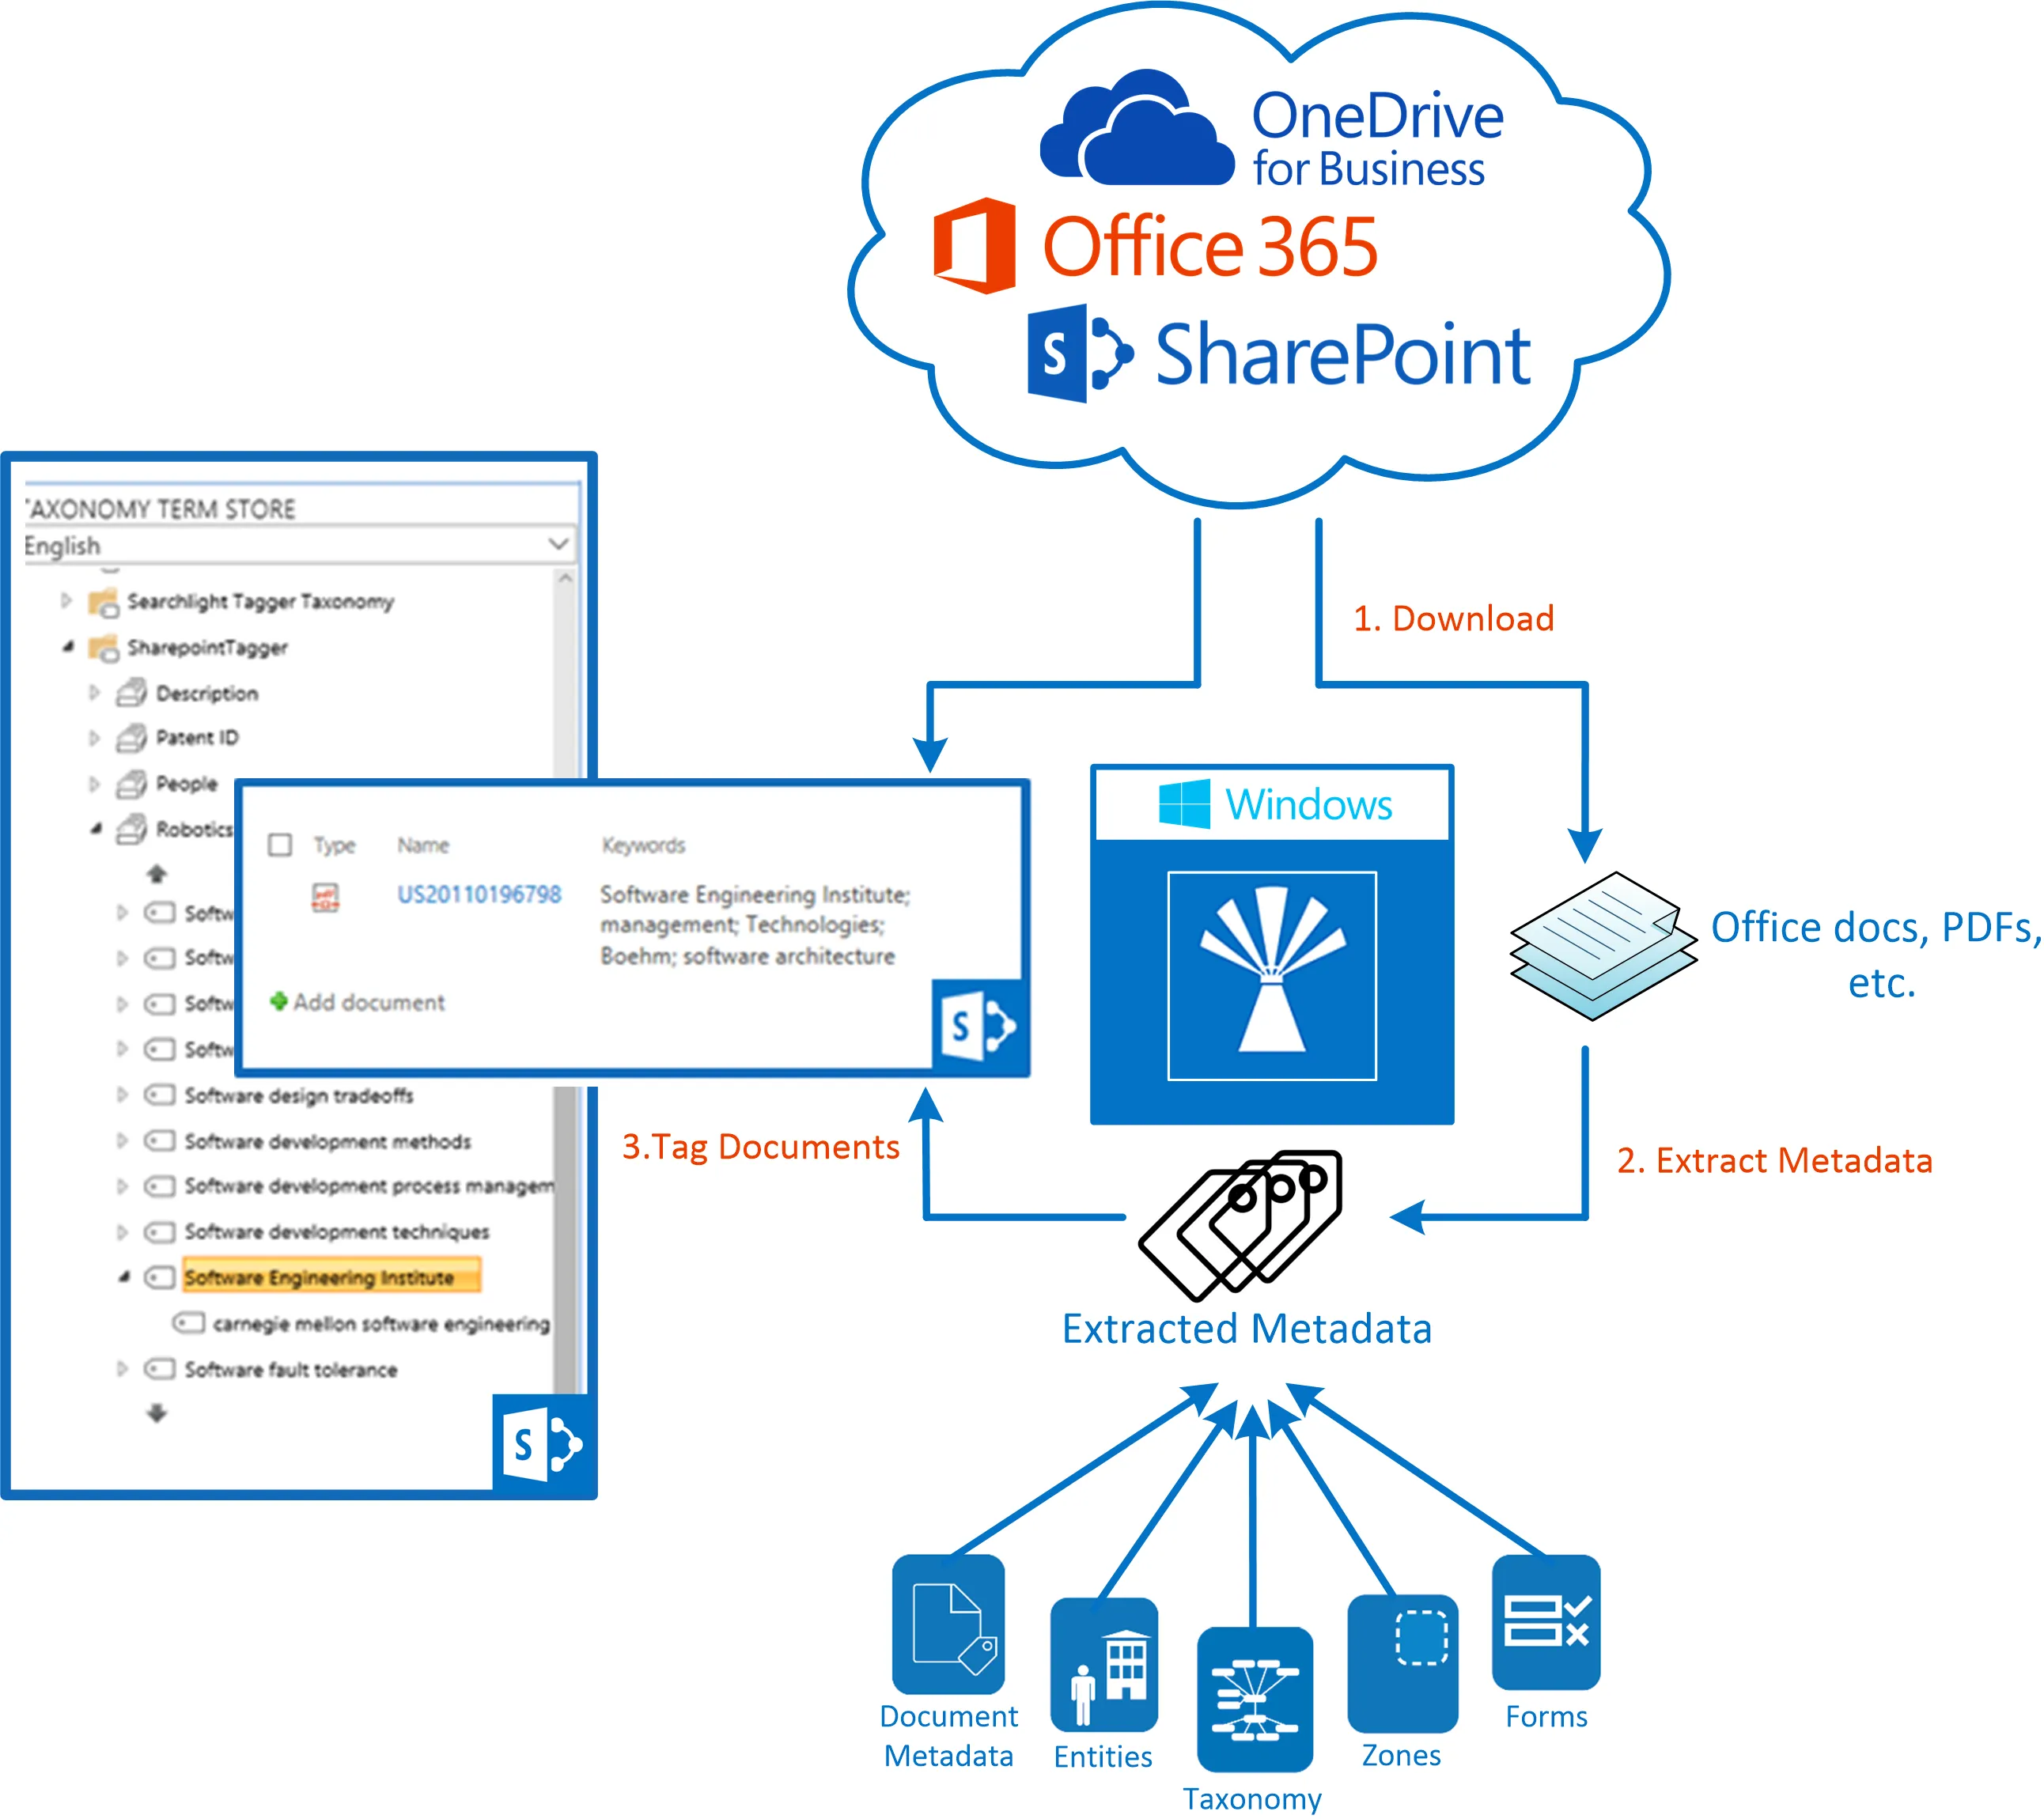
Document Searchability Tagging works in three main steps:
- Documents are downloaded from SharePoint to the temporary location defined in Tagging.
- Metadata are extracted or generated from the documents, following the extraction types selected and the metadata chosen for extraction. The sections below describe each extraction type.
- The documents are then tagged with the metadata from the previous step. Any metadata not already in the Term Store is added to it.
The downloaded documents are deleted after processing.
Taxonomy matching
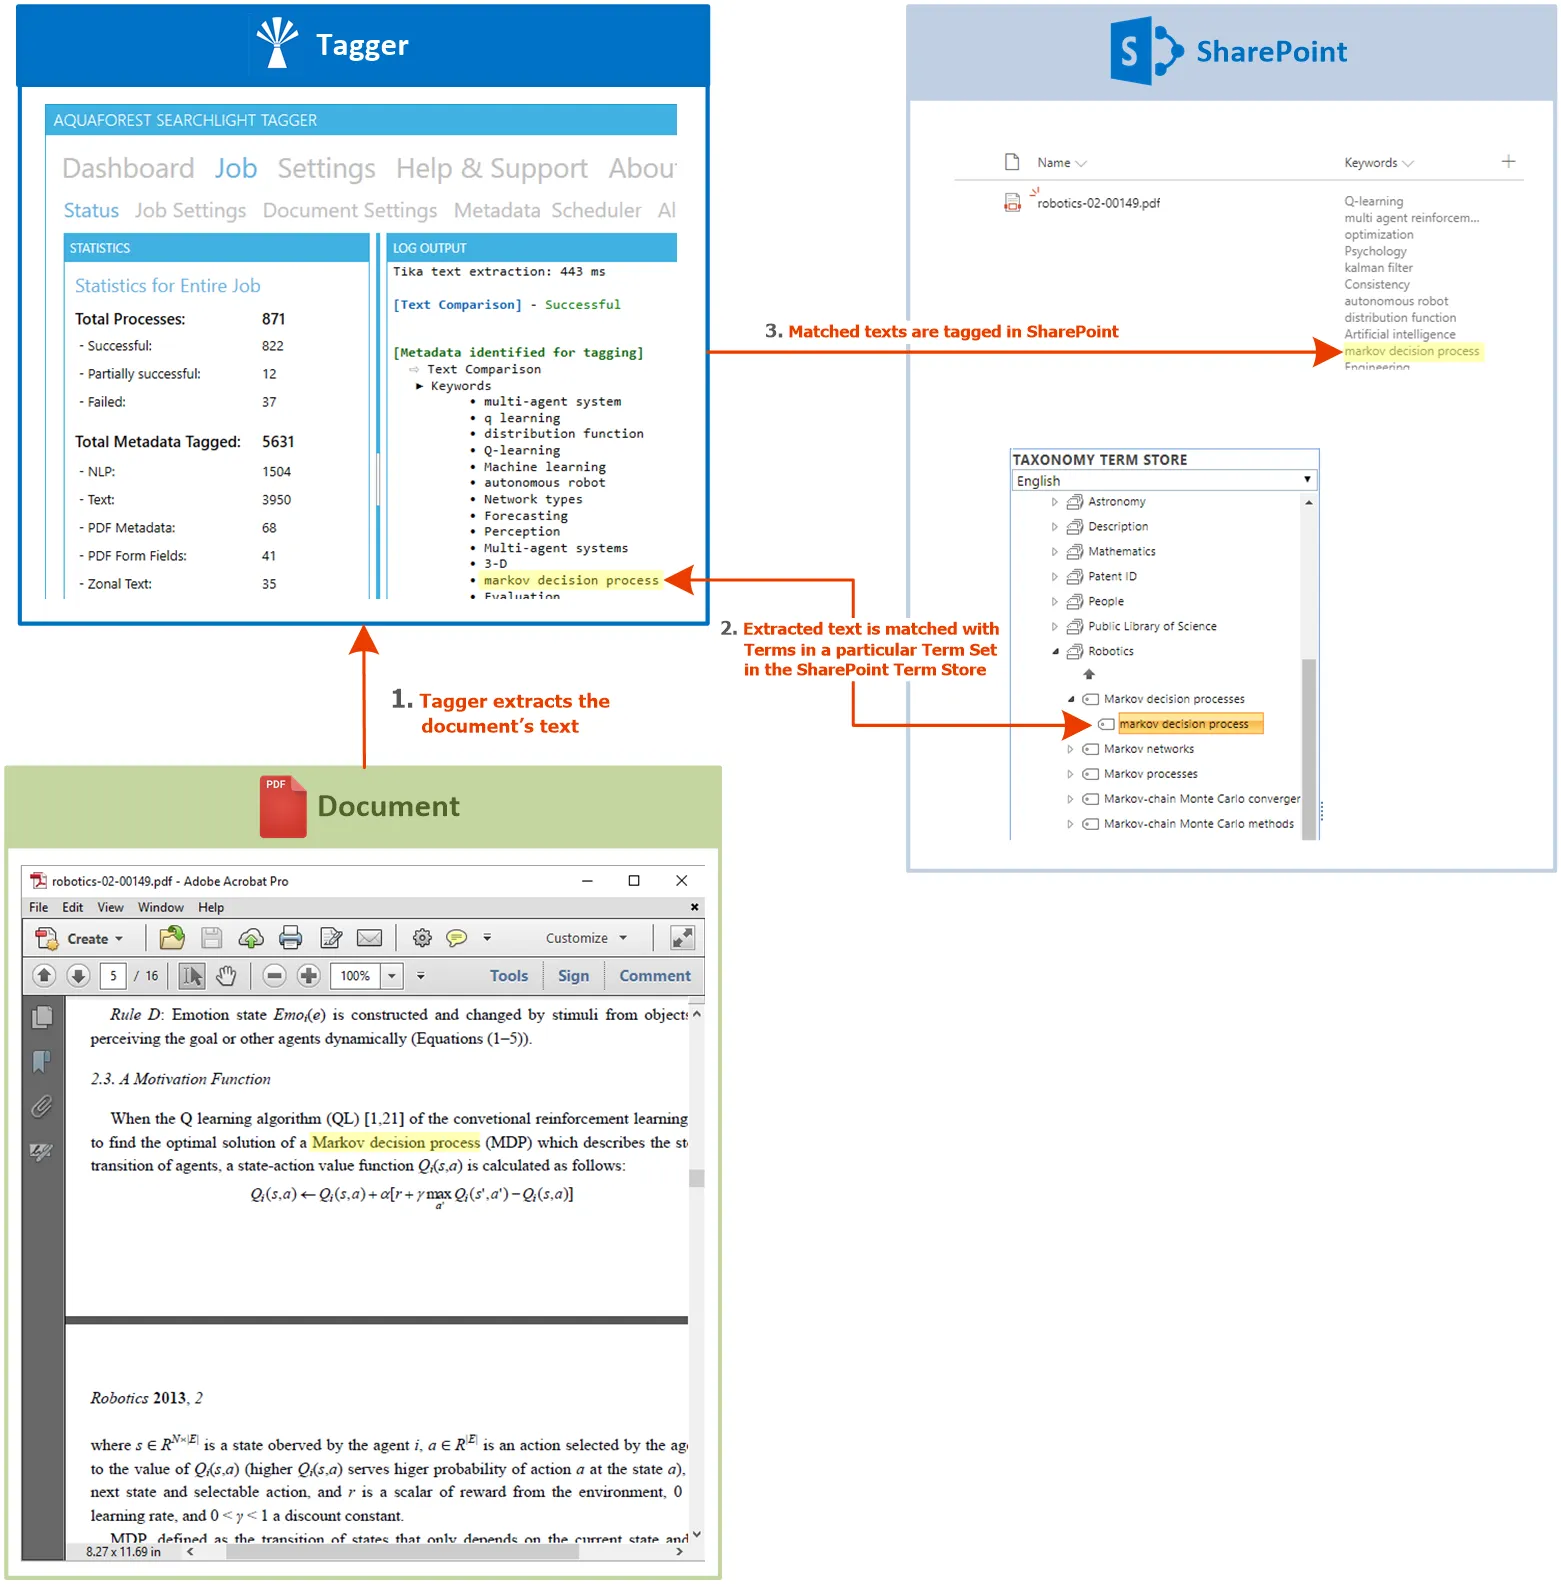
Document Searchability uses managed metadata and taxonomies to identify which taxonomy(opens in a new tab) values should tag a document. It can also add new taxonomy values where they are required. It extracts the text from a document and compares it with the terms in the Taxonomy Term Store. Only the Terms in the Term Set defined for the selected SharePoint column are compared.
Entity extraction
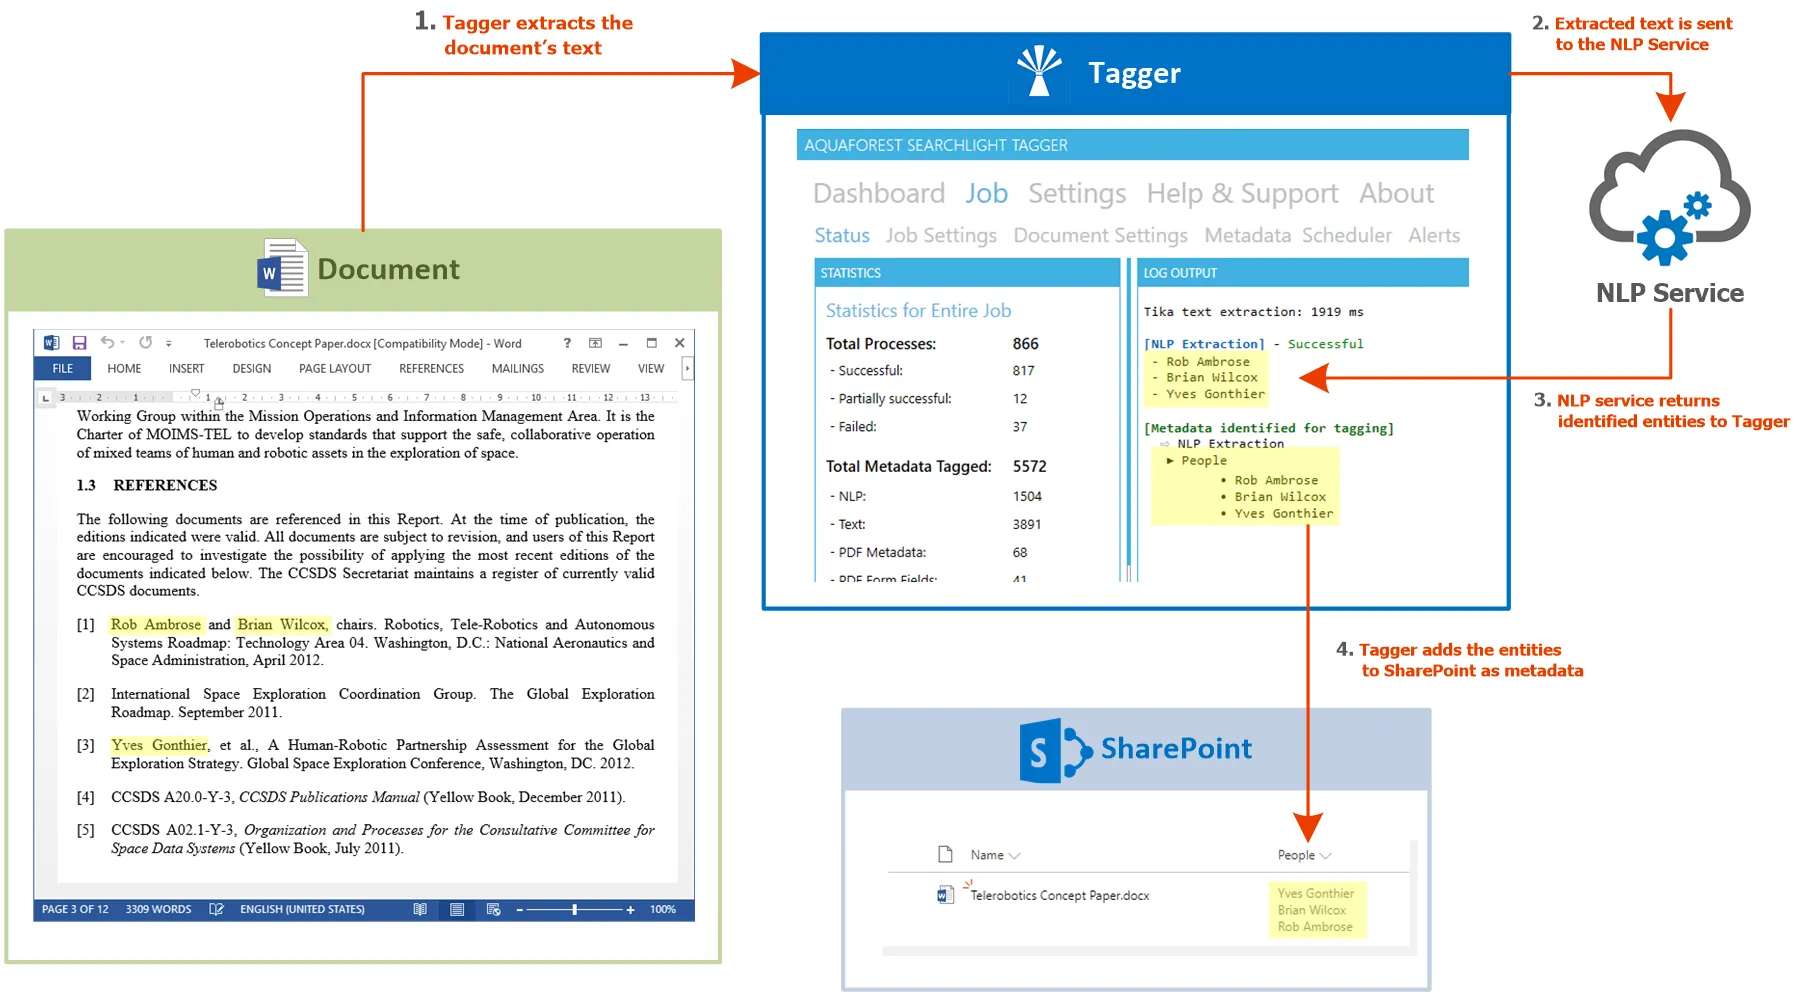
Integration with NLP (Natural Language Processing) services assigns values for Entities such as Location, Person and Company. Tagging extracts the text from a document and passes it to the configured NLP service, which identifies or generates the entities to use as metadata. Section 5.1 covers Entity Extraction in more detail.
Zonal extraction
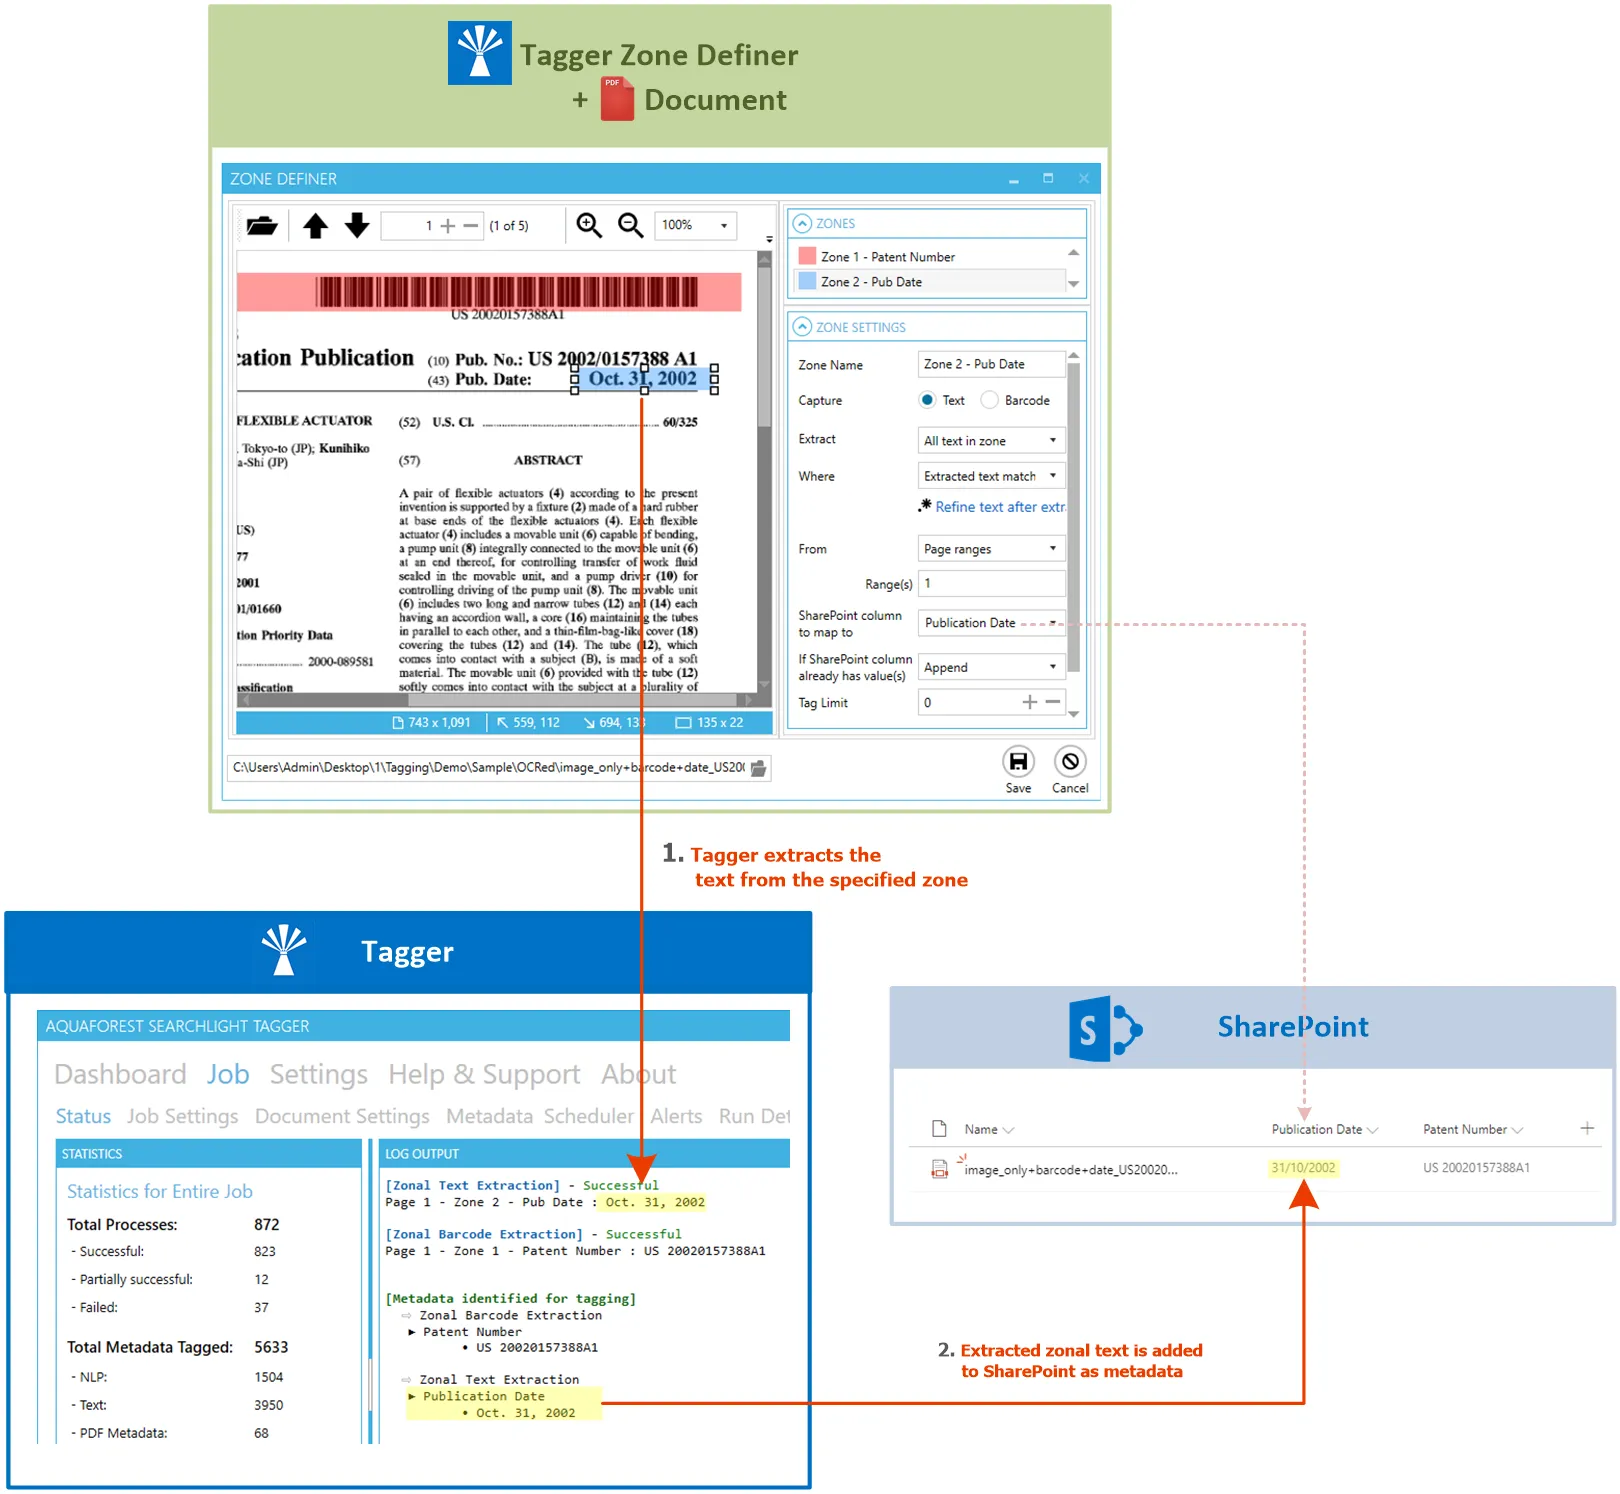
Tagging also extracts text and barcodes from a defined zone of a PDF document. It recognizes over 20 types of barcode and assigns their values to Library metadata columns.
Document metadata
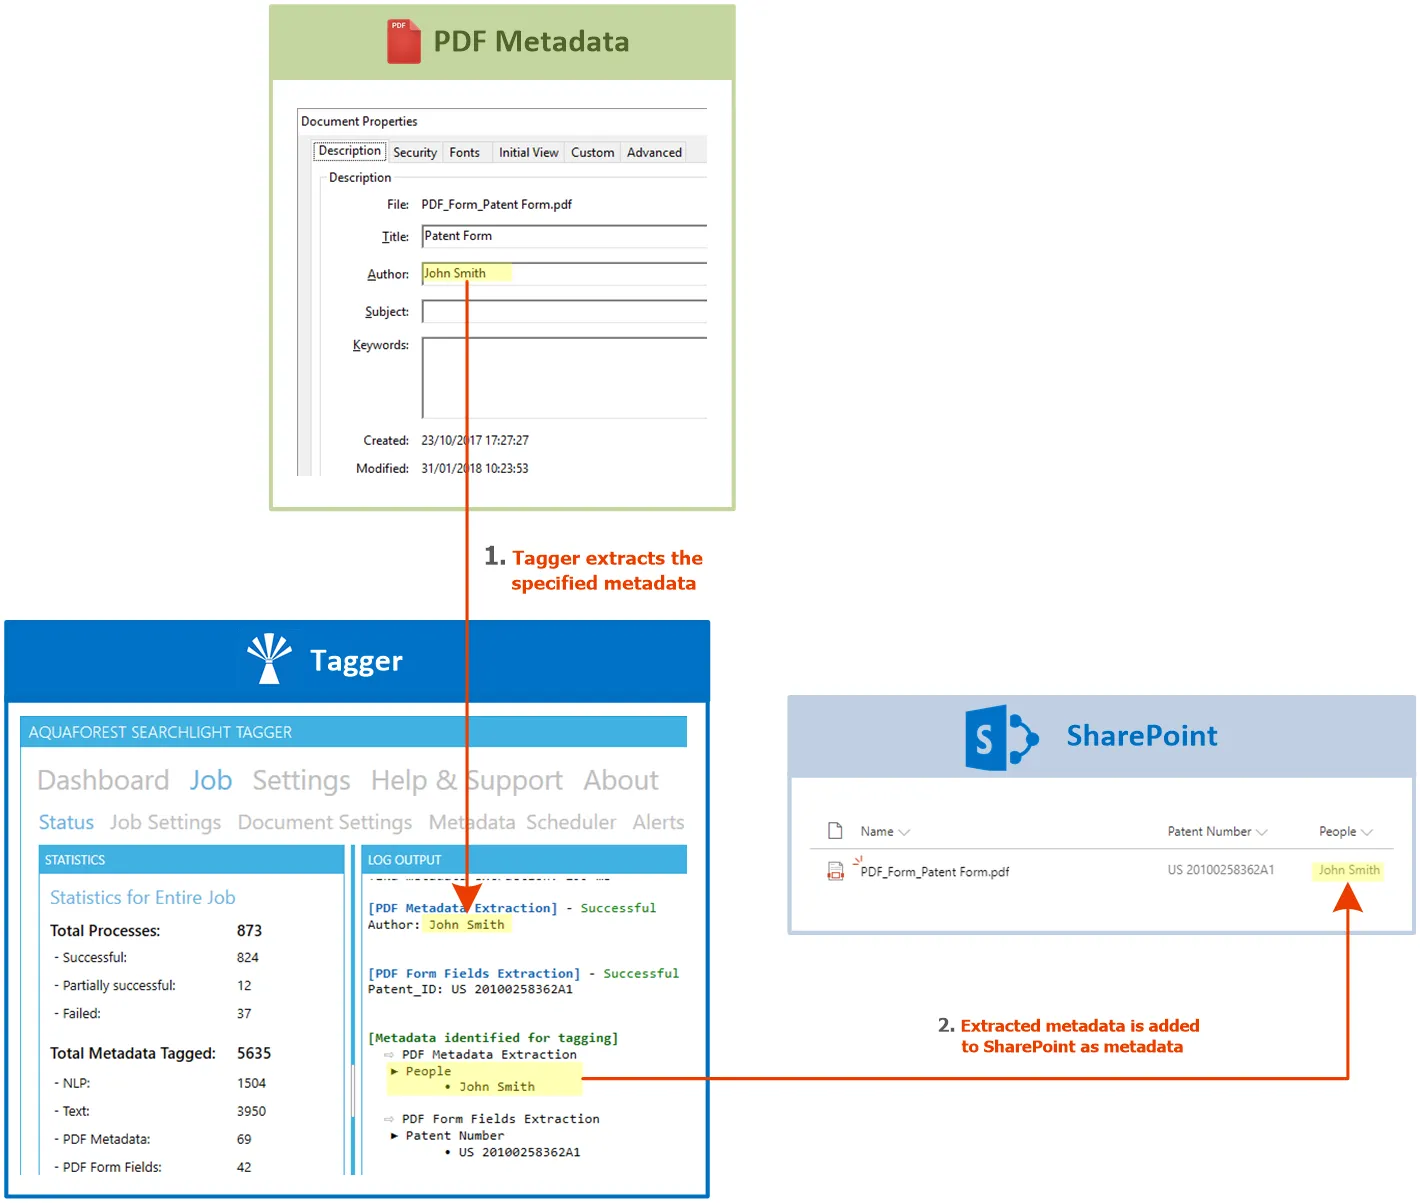
Standard PDF metadata, custom PDF metadata and XMP metadata can all be extracted and assigned to SharePoint columns.
PDF forms
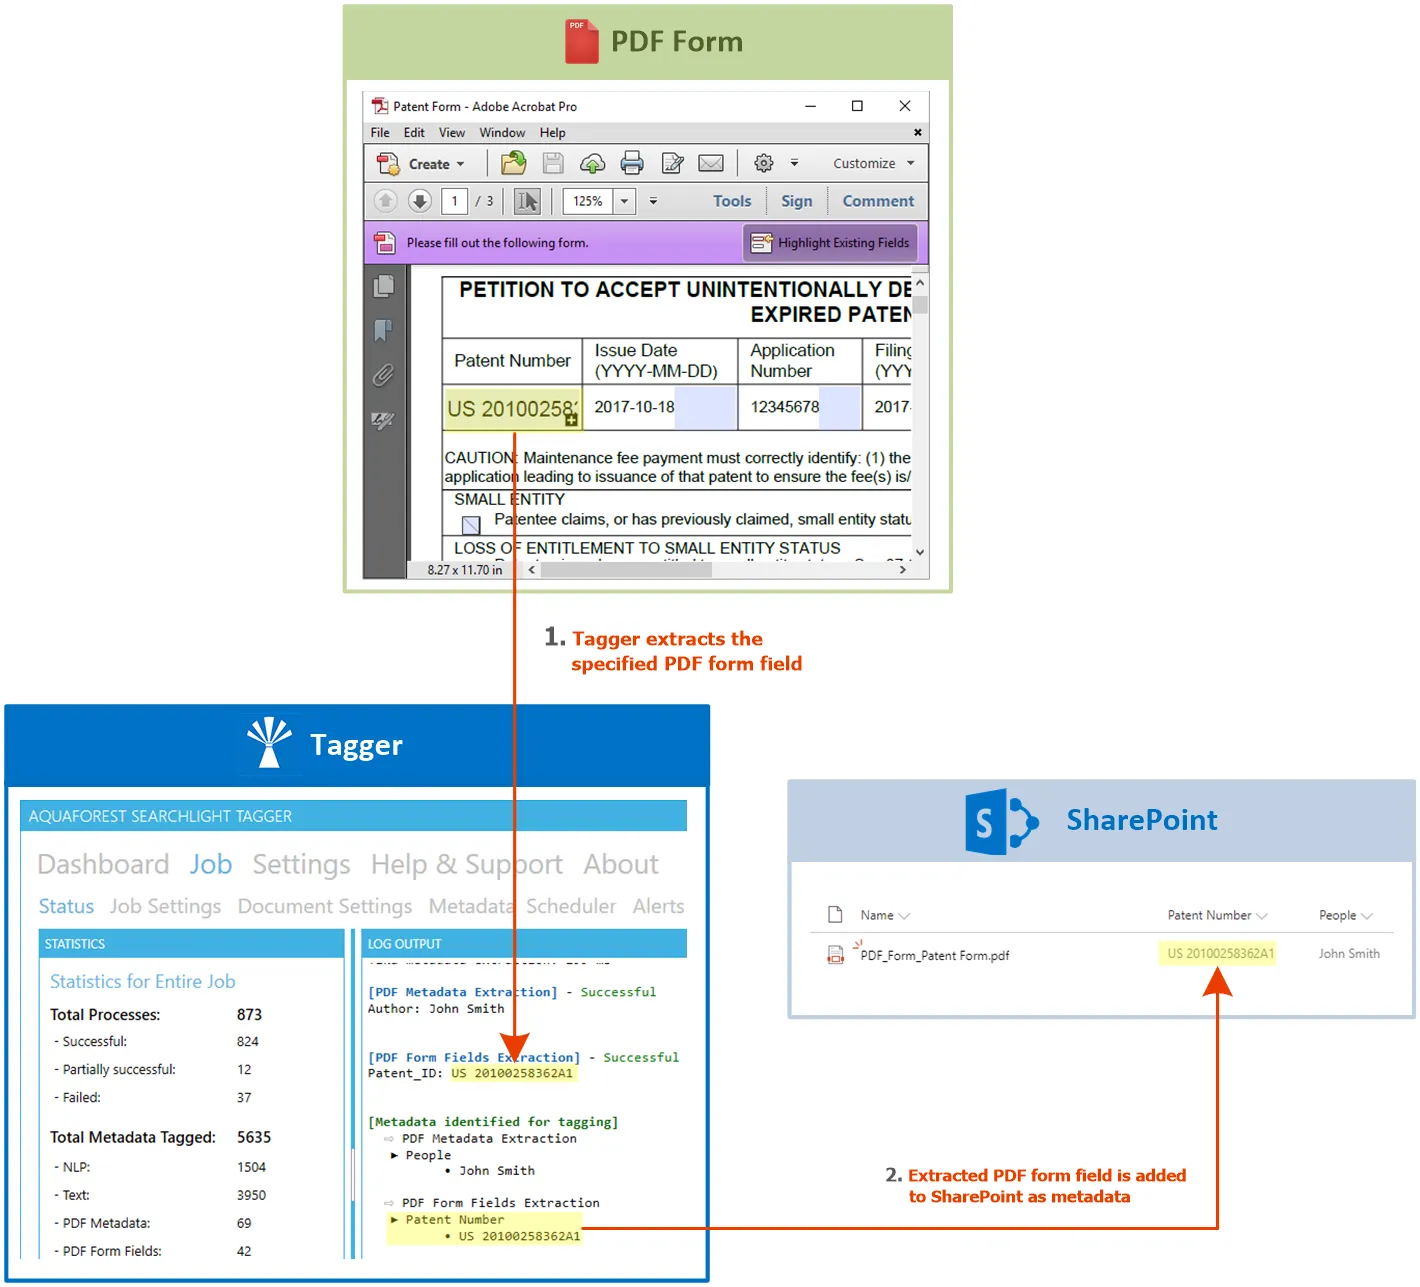
Data from a PDF form can be extracted, with each field value assigned to its own SharePoint column.